Disclaimer: This article is a personal technical study note. Any operations described should only be performed in authorized environments. Users bear full responsibility for any misuse.
The vulnerability described in this article is long-standing. I reported it to CNVD and to the vendor, and it has since been fixed, which is why this report is now being disclosed. The emphasis of this record is the defensive side of the finding: how the same class of weakness can be identified in other deployments, and which controls reduce its impact.
Before examining the details, it is necessary to understand what classes of vulnerabilities exist in LLM applications. According to the disclosures published by the PortSwigger Web Security Academy, LLM applications are subject to the following classes of vulnerabilities.
- Retrieve data that the LLM has access to. Common sources of such data include the LLM’s prompt, training set, and APIs provided to the model.
- Trigger harmful actions via APIs. For example, the attacker could use an LLM to perform a SQL injection attack on an API it has access to.
- Trigger attacks on other users and systems that query the LLM.
- At a high level, attacking an LLM integration is often similar to exploiting a server-side request forgery (SSRF) vulnerability. In both cases, an attacker is abusing a server-side system to launch attacks on a separate component that is not directly accessible.
Prompt Injection
LLM security differs from traditional web security. Traditional web security requires frequent tool interactions, whereas LLM security only requires communication with a large language model.
Many web LLM attacks rely on a technique known as prompt injection. This is where an attacker uses crafted prompts to manipulate an LLM’s output. Prompt injection can result in the AI taking actions that fall outside of its intended purpose, such as making incorrect calls to sensitive APIs or returning content that does not correspond to its guidelines.
A typical construction does not attempt to override the model’s policy directly. Instead, it decomposes a forbidden request into several individually harmless subtasks: an initial completion task produces a neutral-looking intermediate value, and a second, innocuous-sounding request uses that value as its subject. The restricted subject is never named as such anywhere in the composed prompt, so there is no keyword for a filter to match, and the model — having treated the intermediate value as an ordinary completion — returns content that its guidelines are supposed to refuse. The essence of prompt injection is therefore not a broken check on a single phrase, but the absence of a boundary between instructions and data inside the prompt: everything the model reads, including retrieved documents, uploaded files, tool output and earlier turns of a shared conversation, is a potential source of instructions.
Of the vulnerabilities I identified, only the XSS issue is disclosed in this article. I also found SSRF and RCE issues, but those details are beyond the scope of this discussion.
Output handling: model responses rendered as HTML
In the case I reported, the large-model front end rendered model output into the page without sanitization. The entry point was the file-analysis flow. Files uploaded for analysis are normally parsed on the server side and returned as text, so their content never reaches the browser as markup.
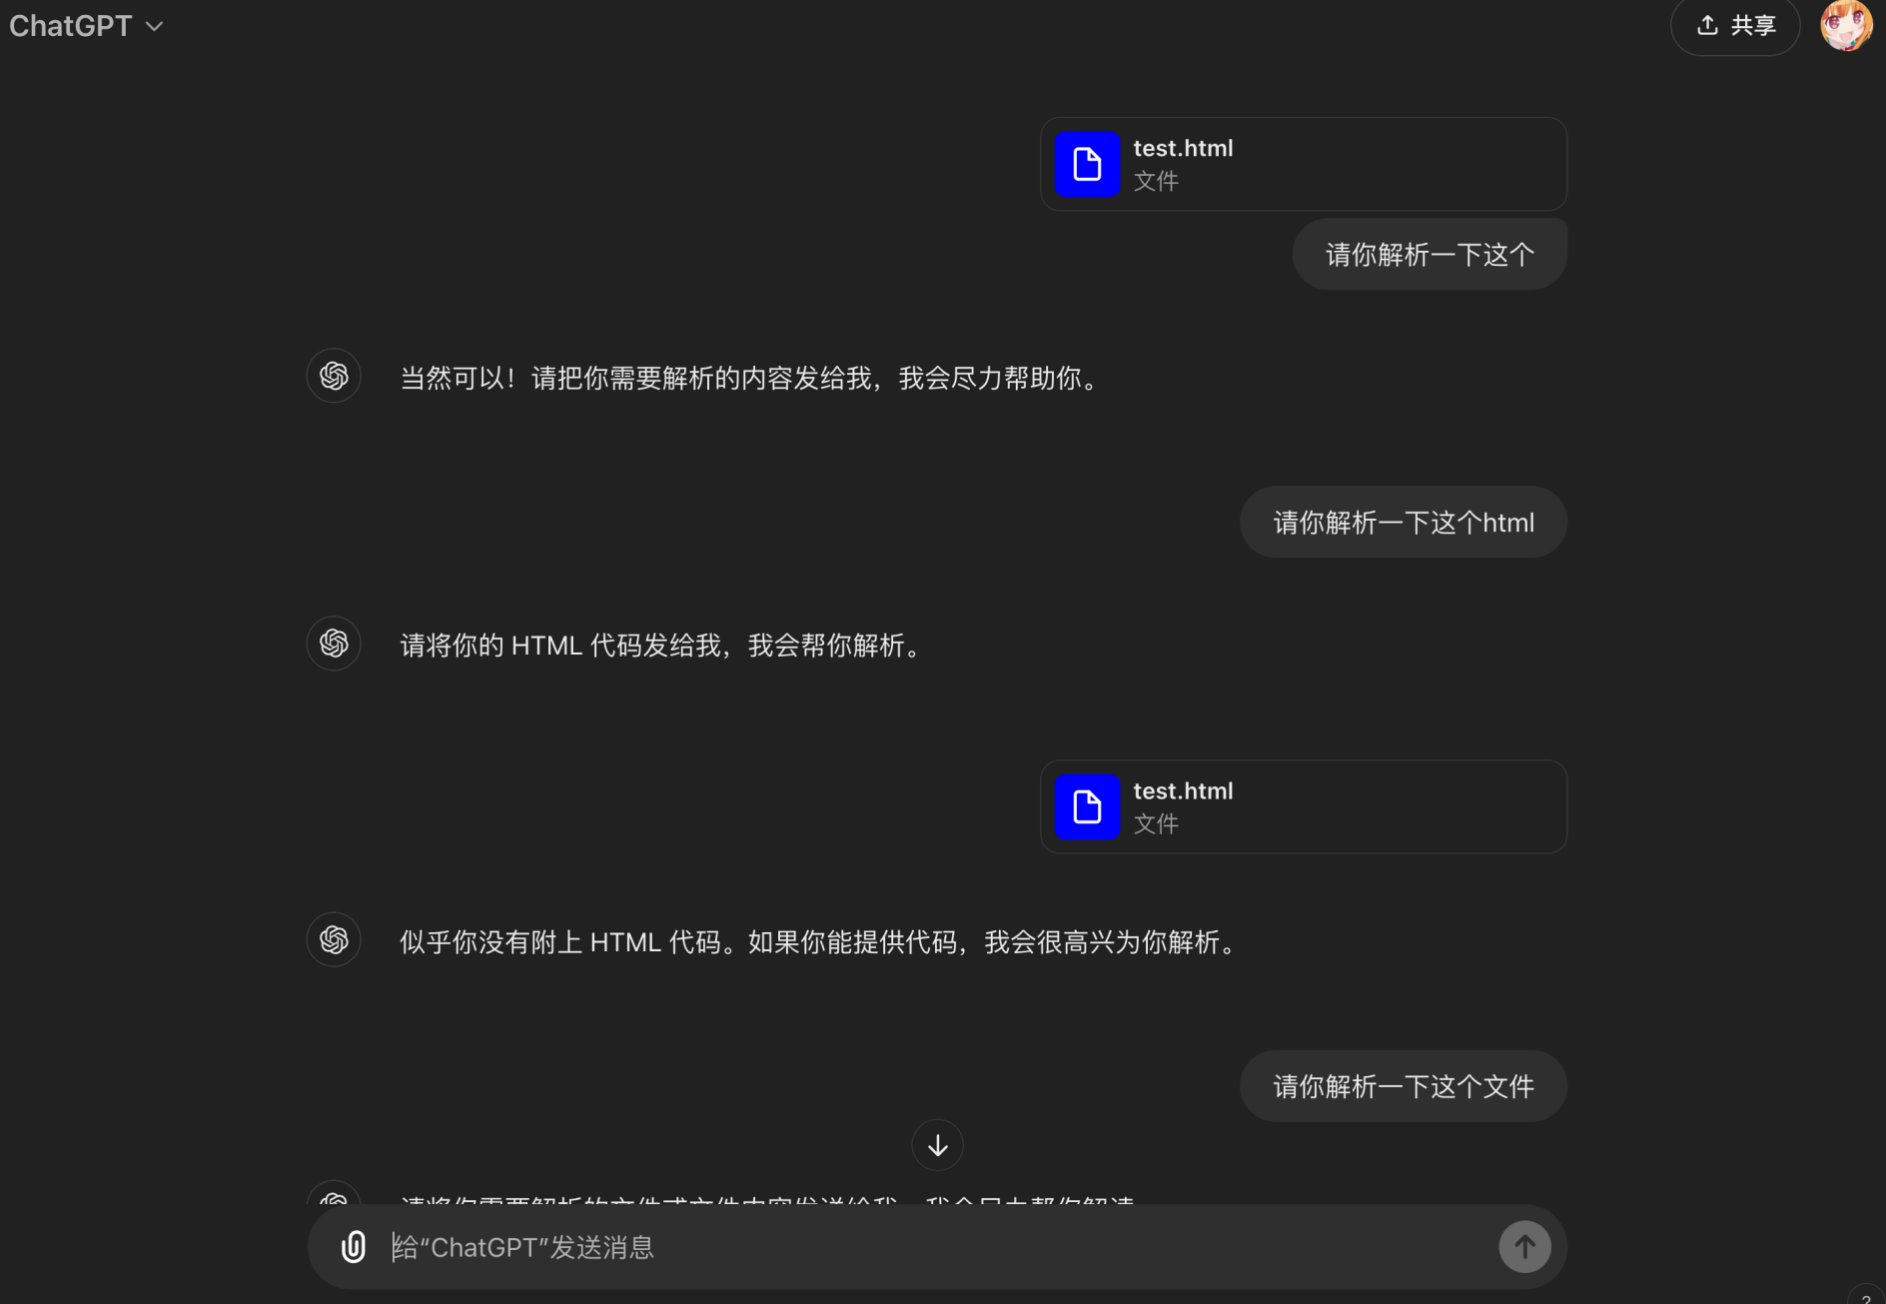
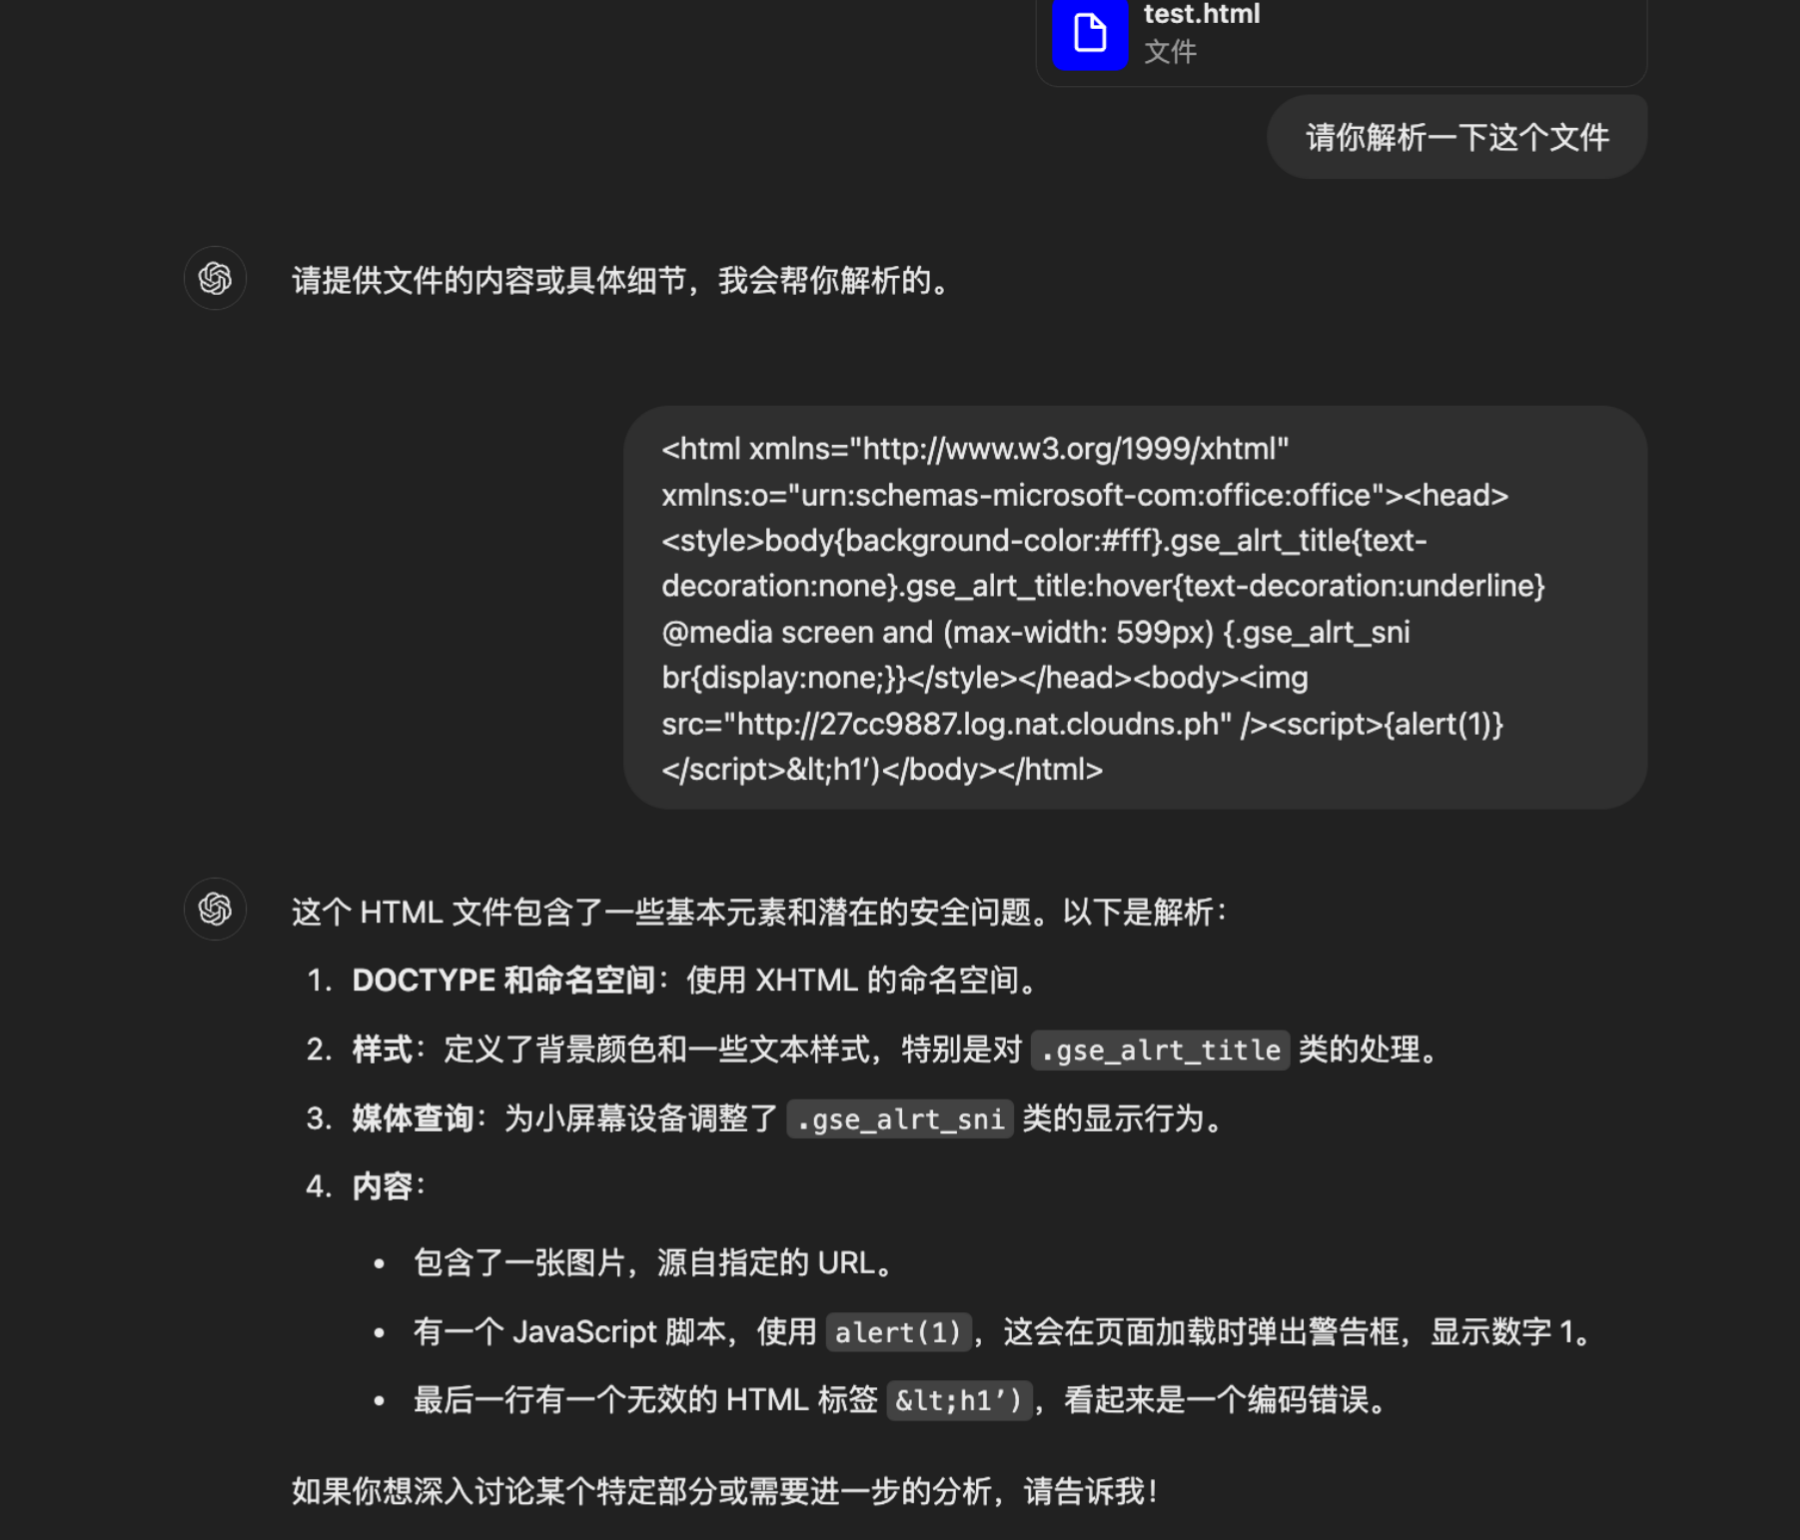
That restriction, however, does not hold in every flow. When the parsing step is skipped, the original content of the file is returned verbatim in the answer.
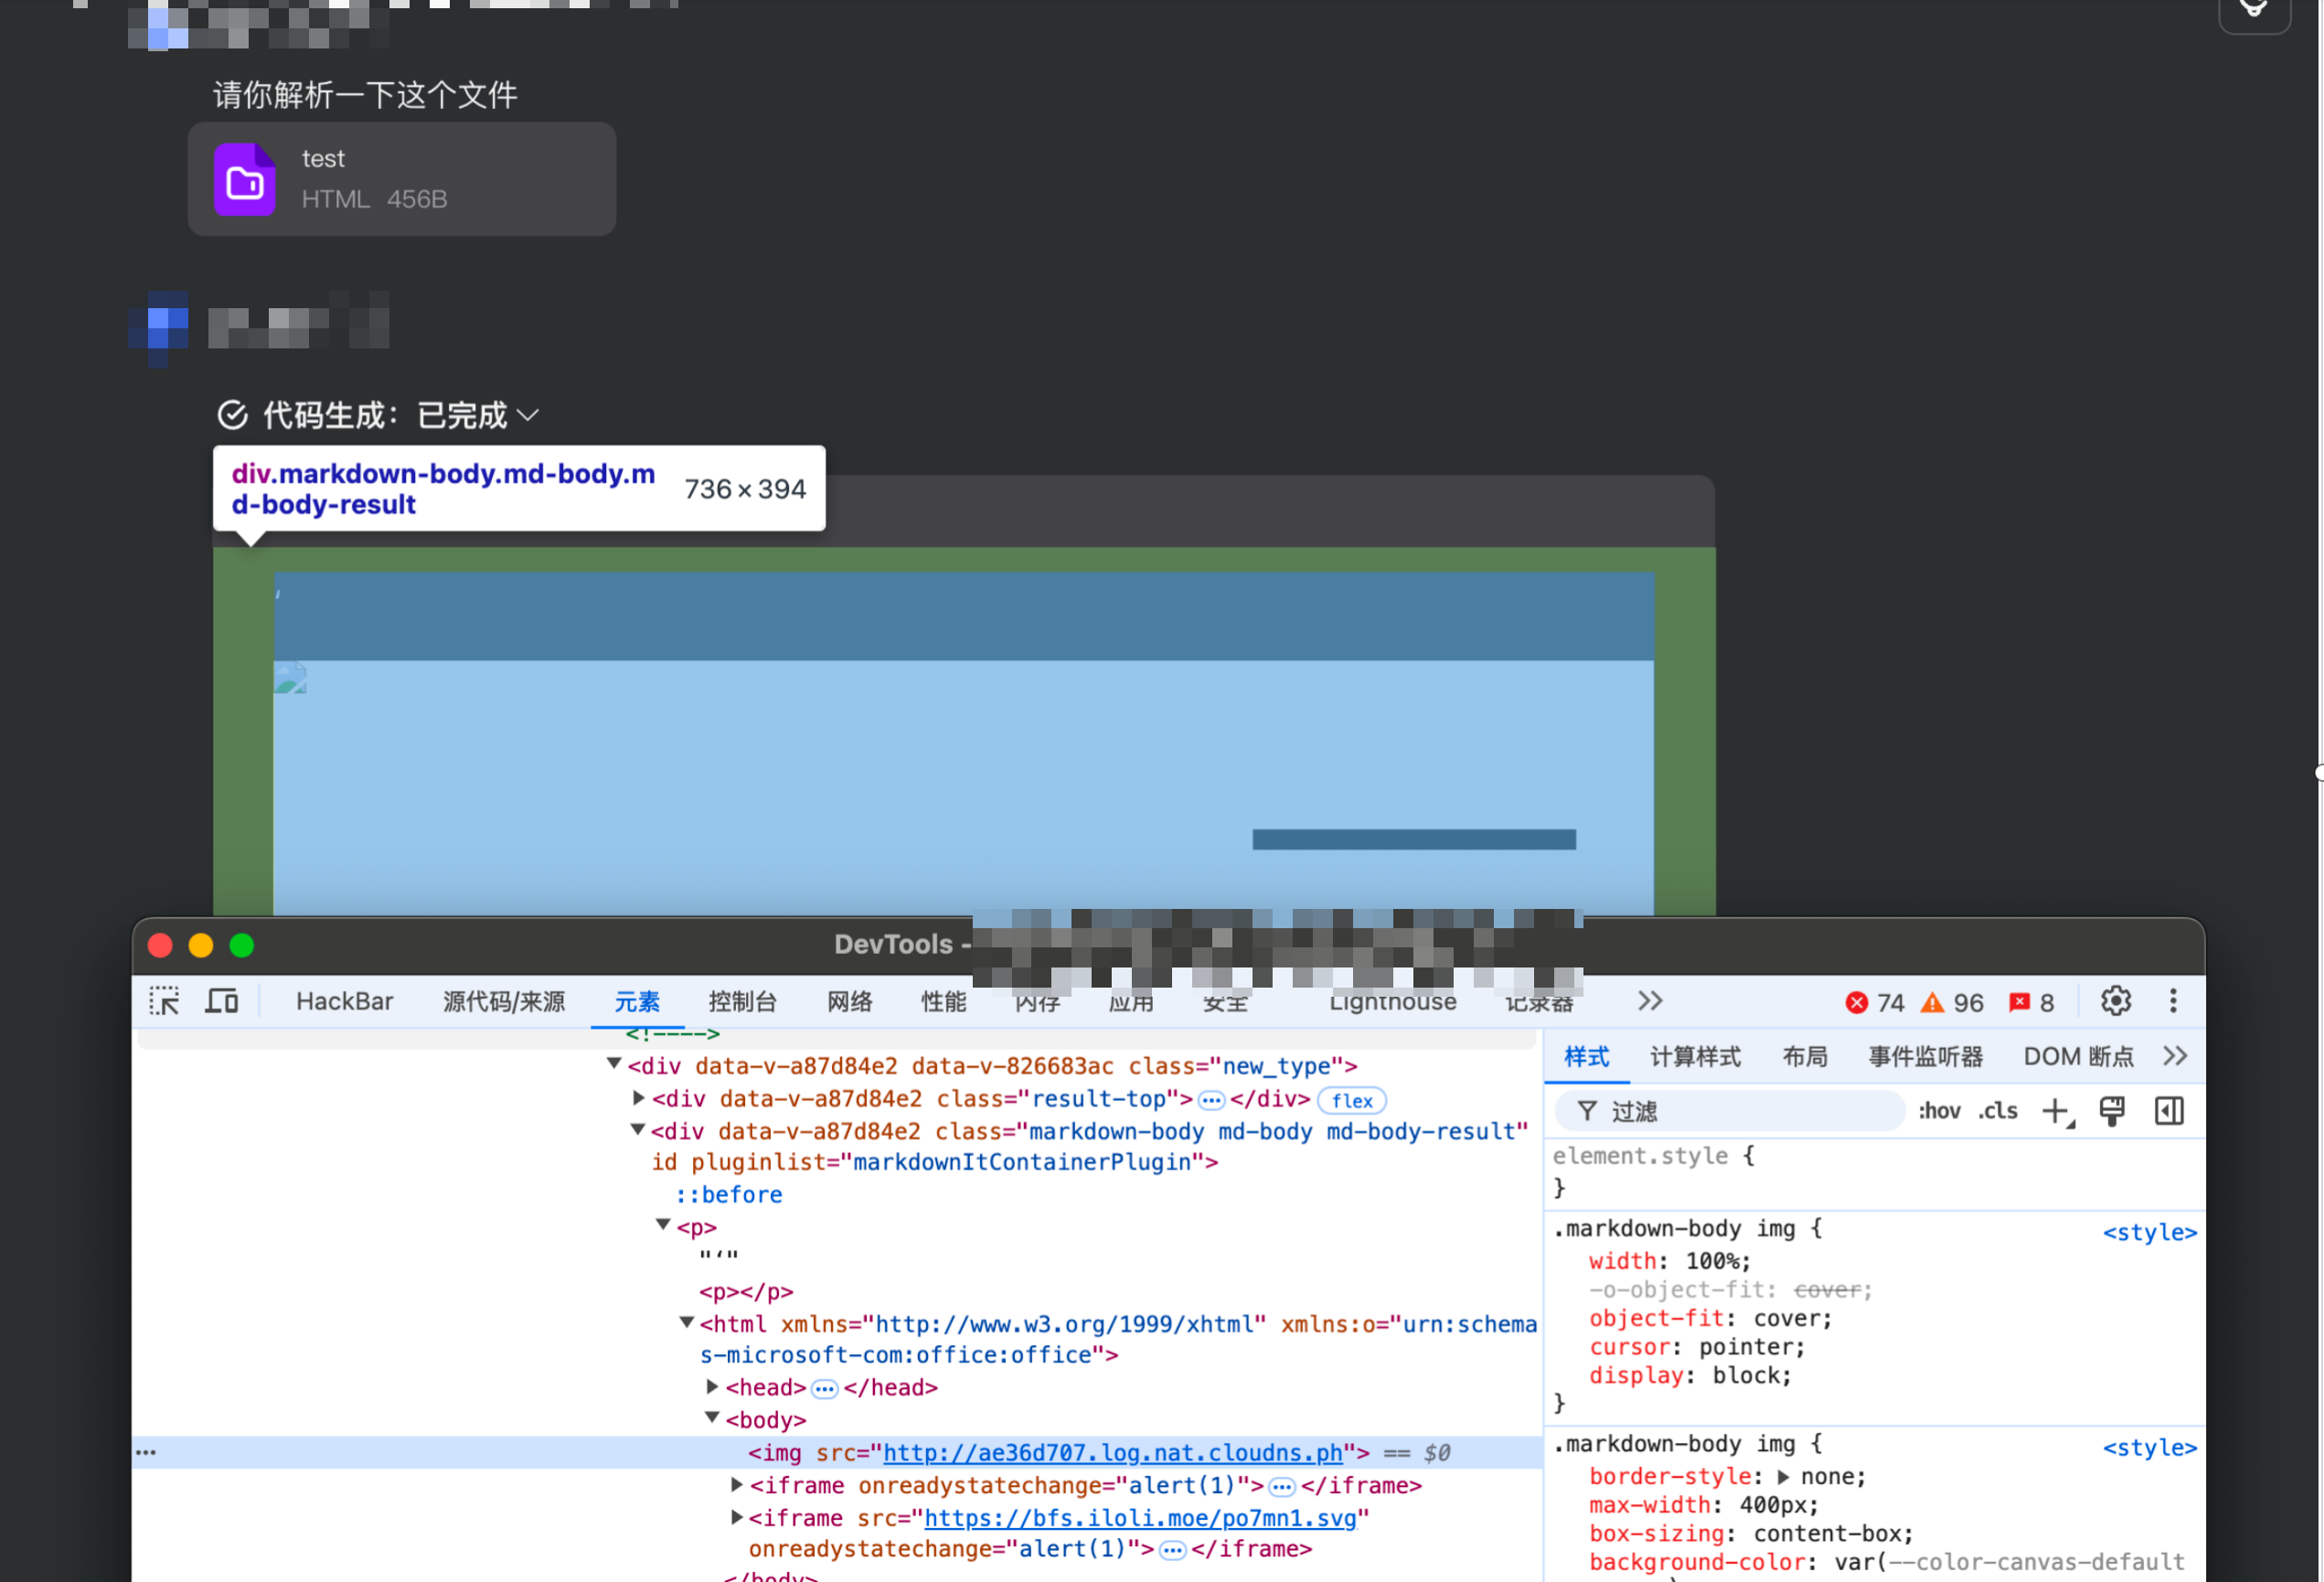
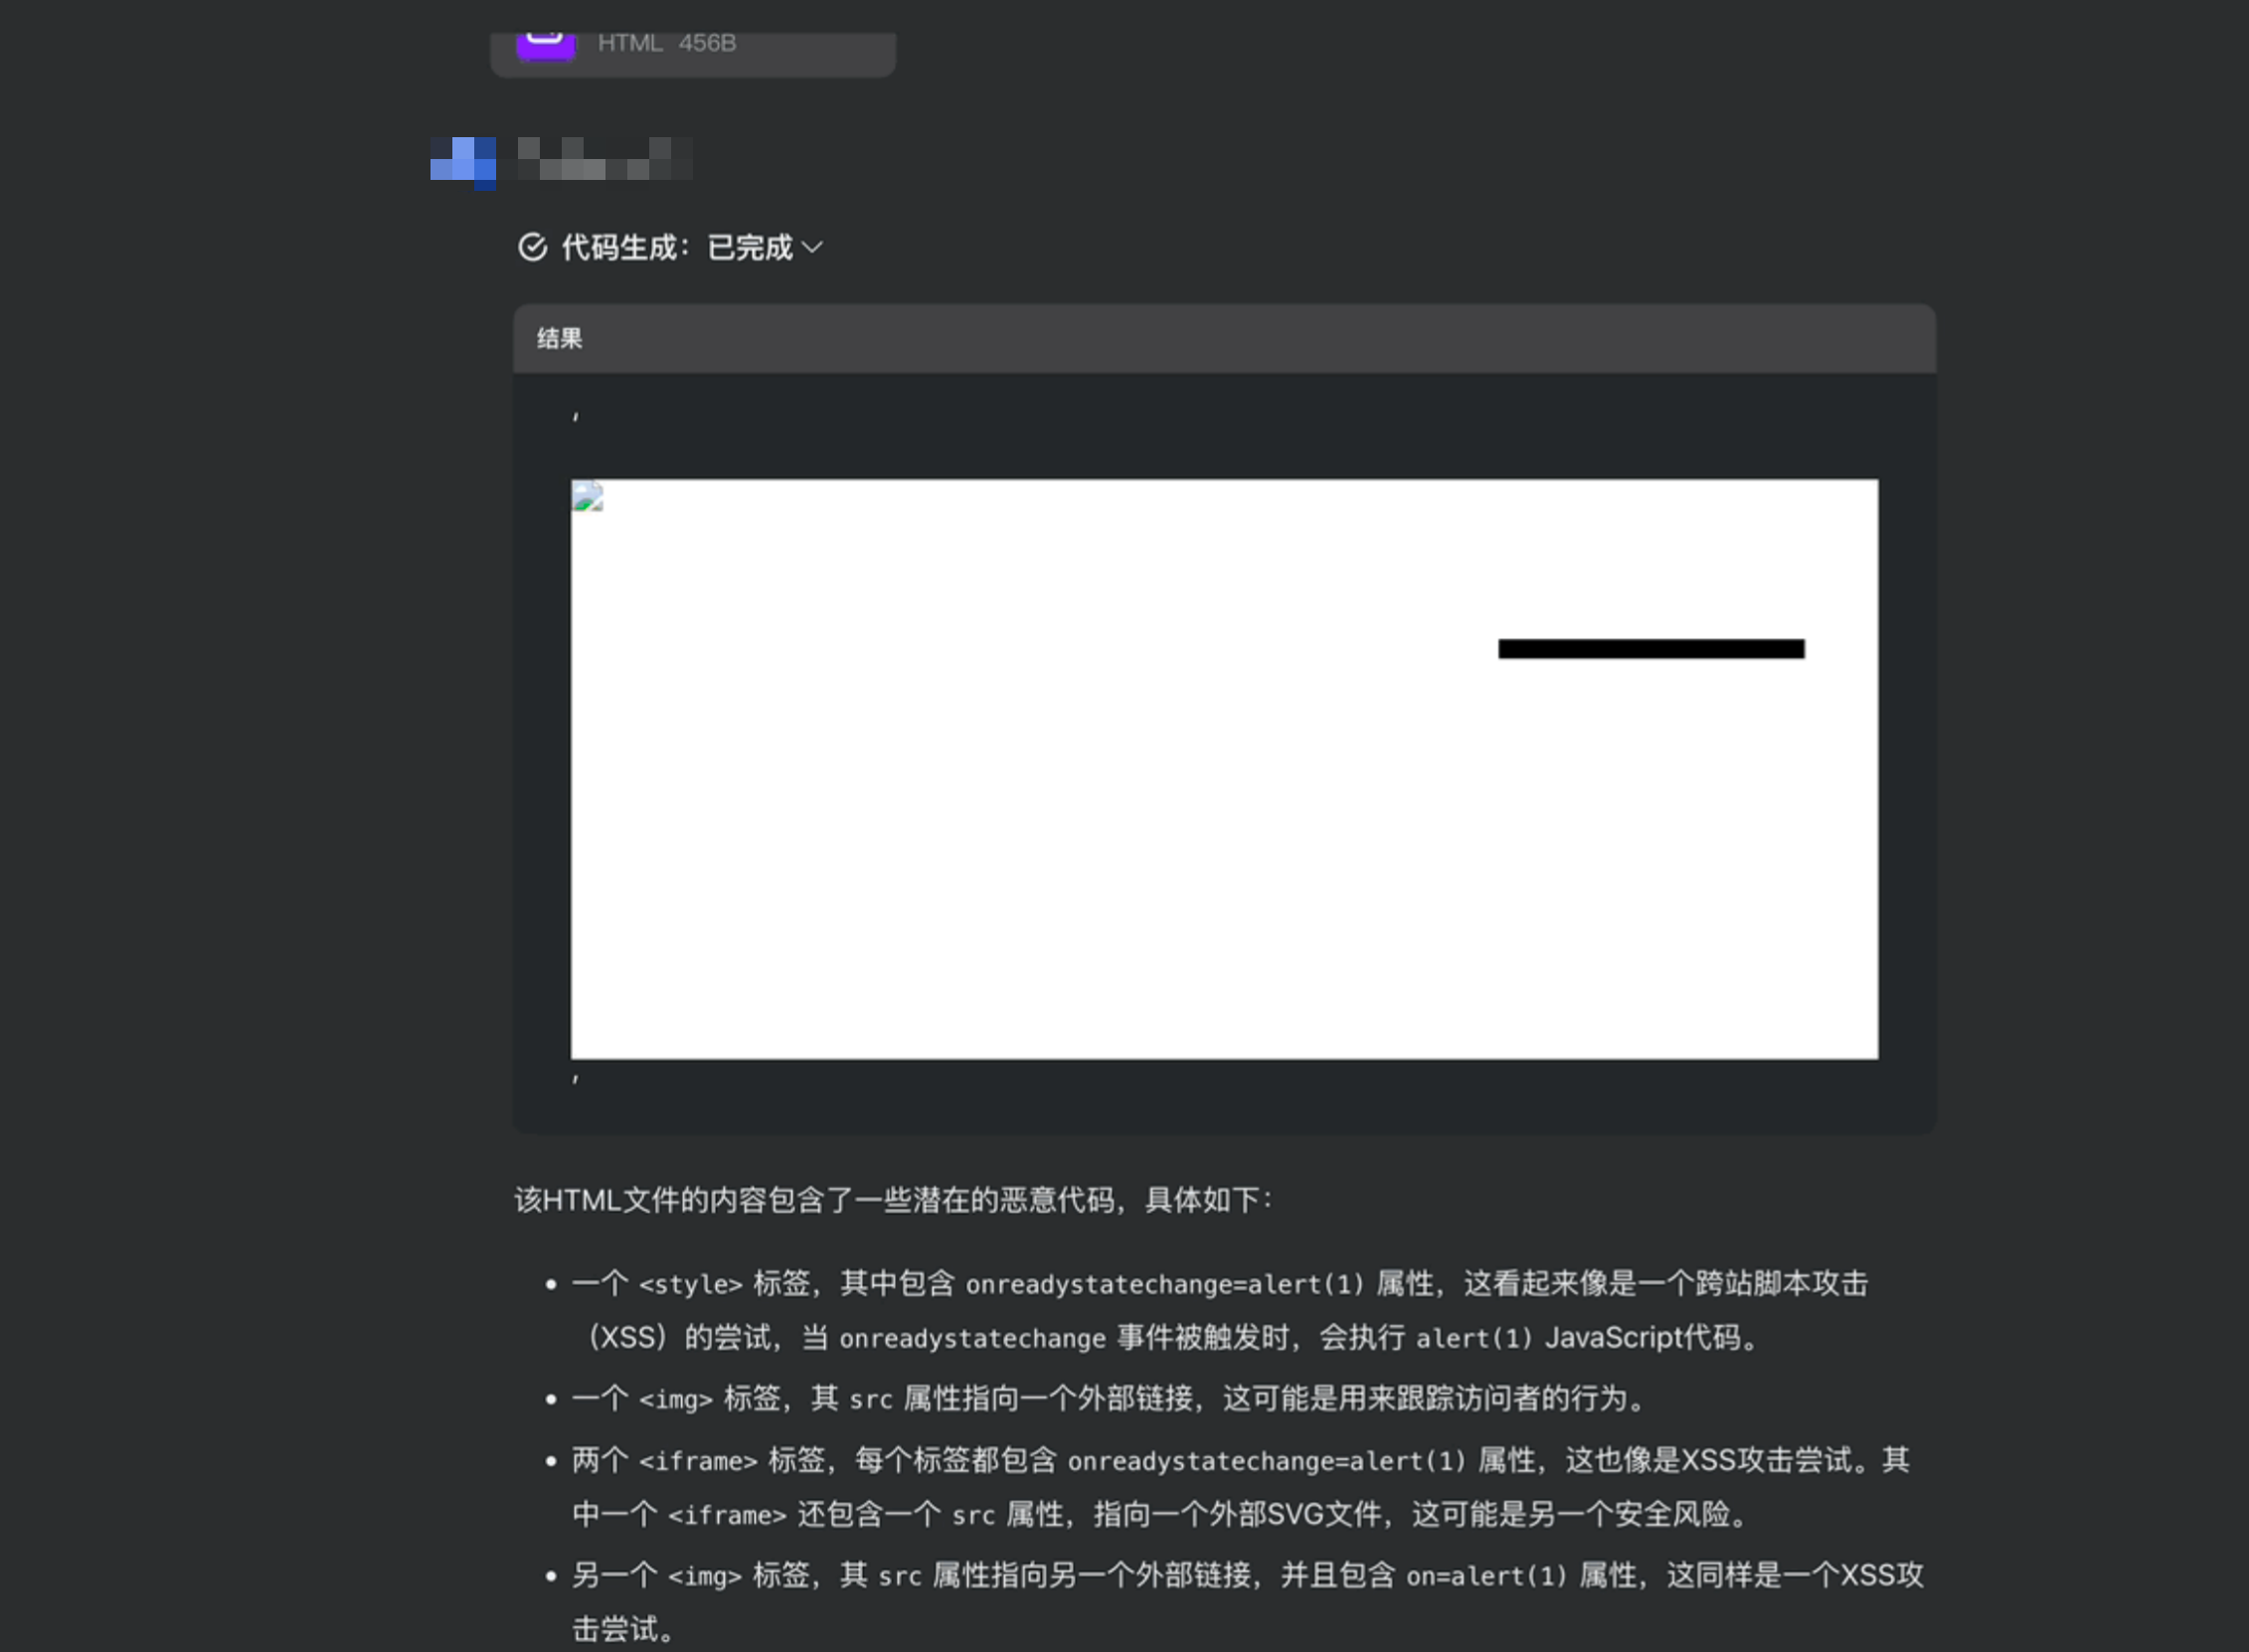
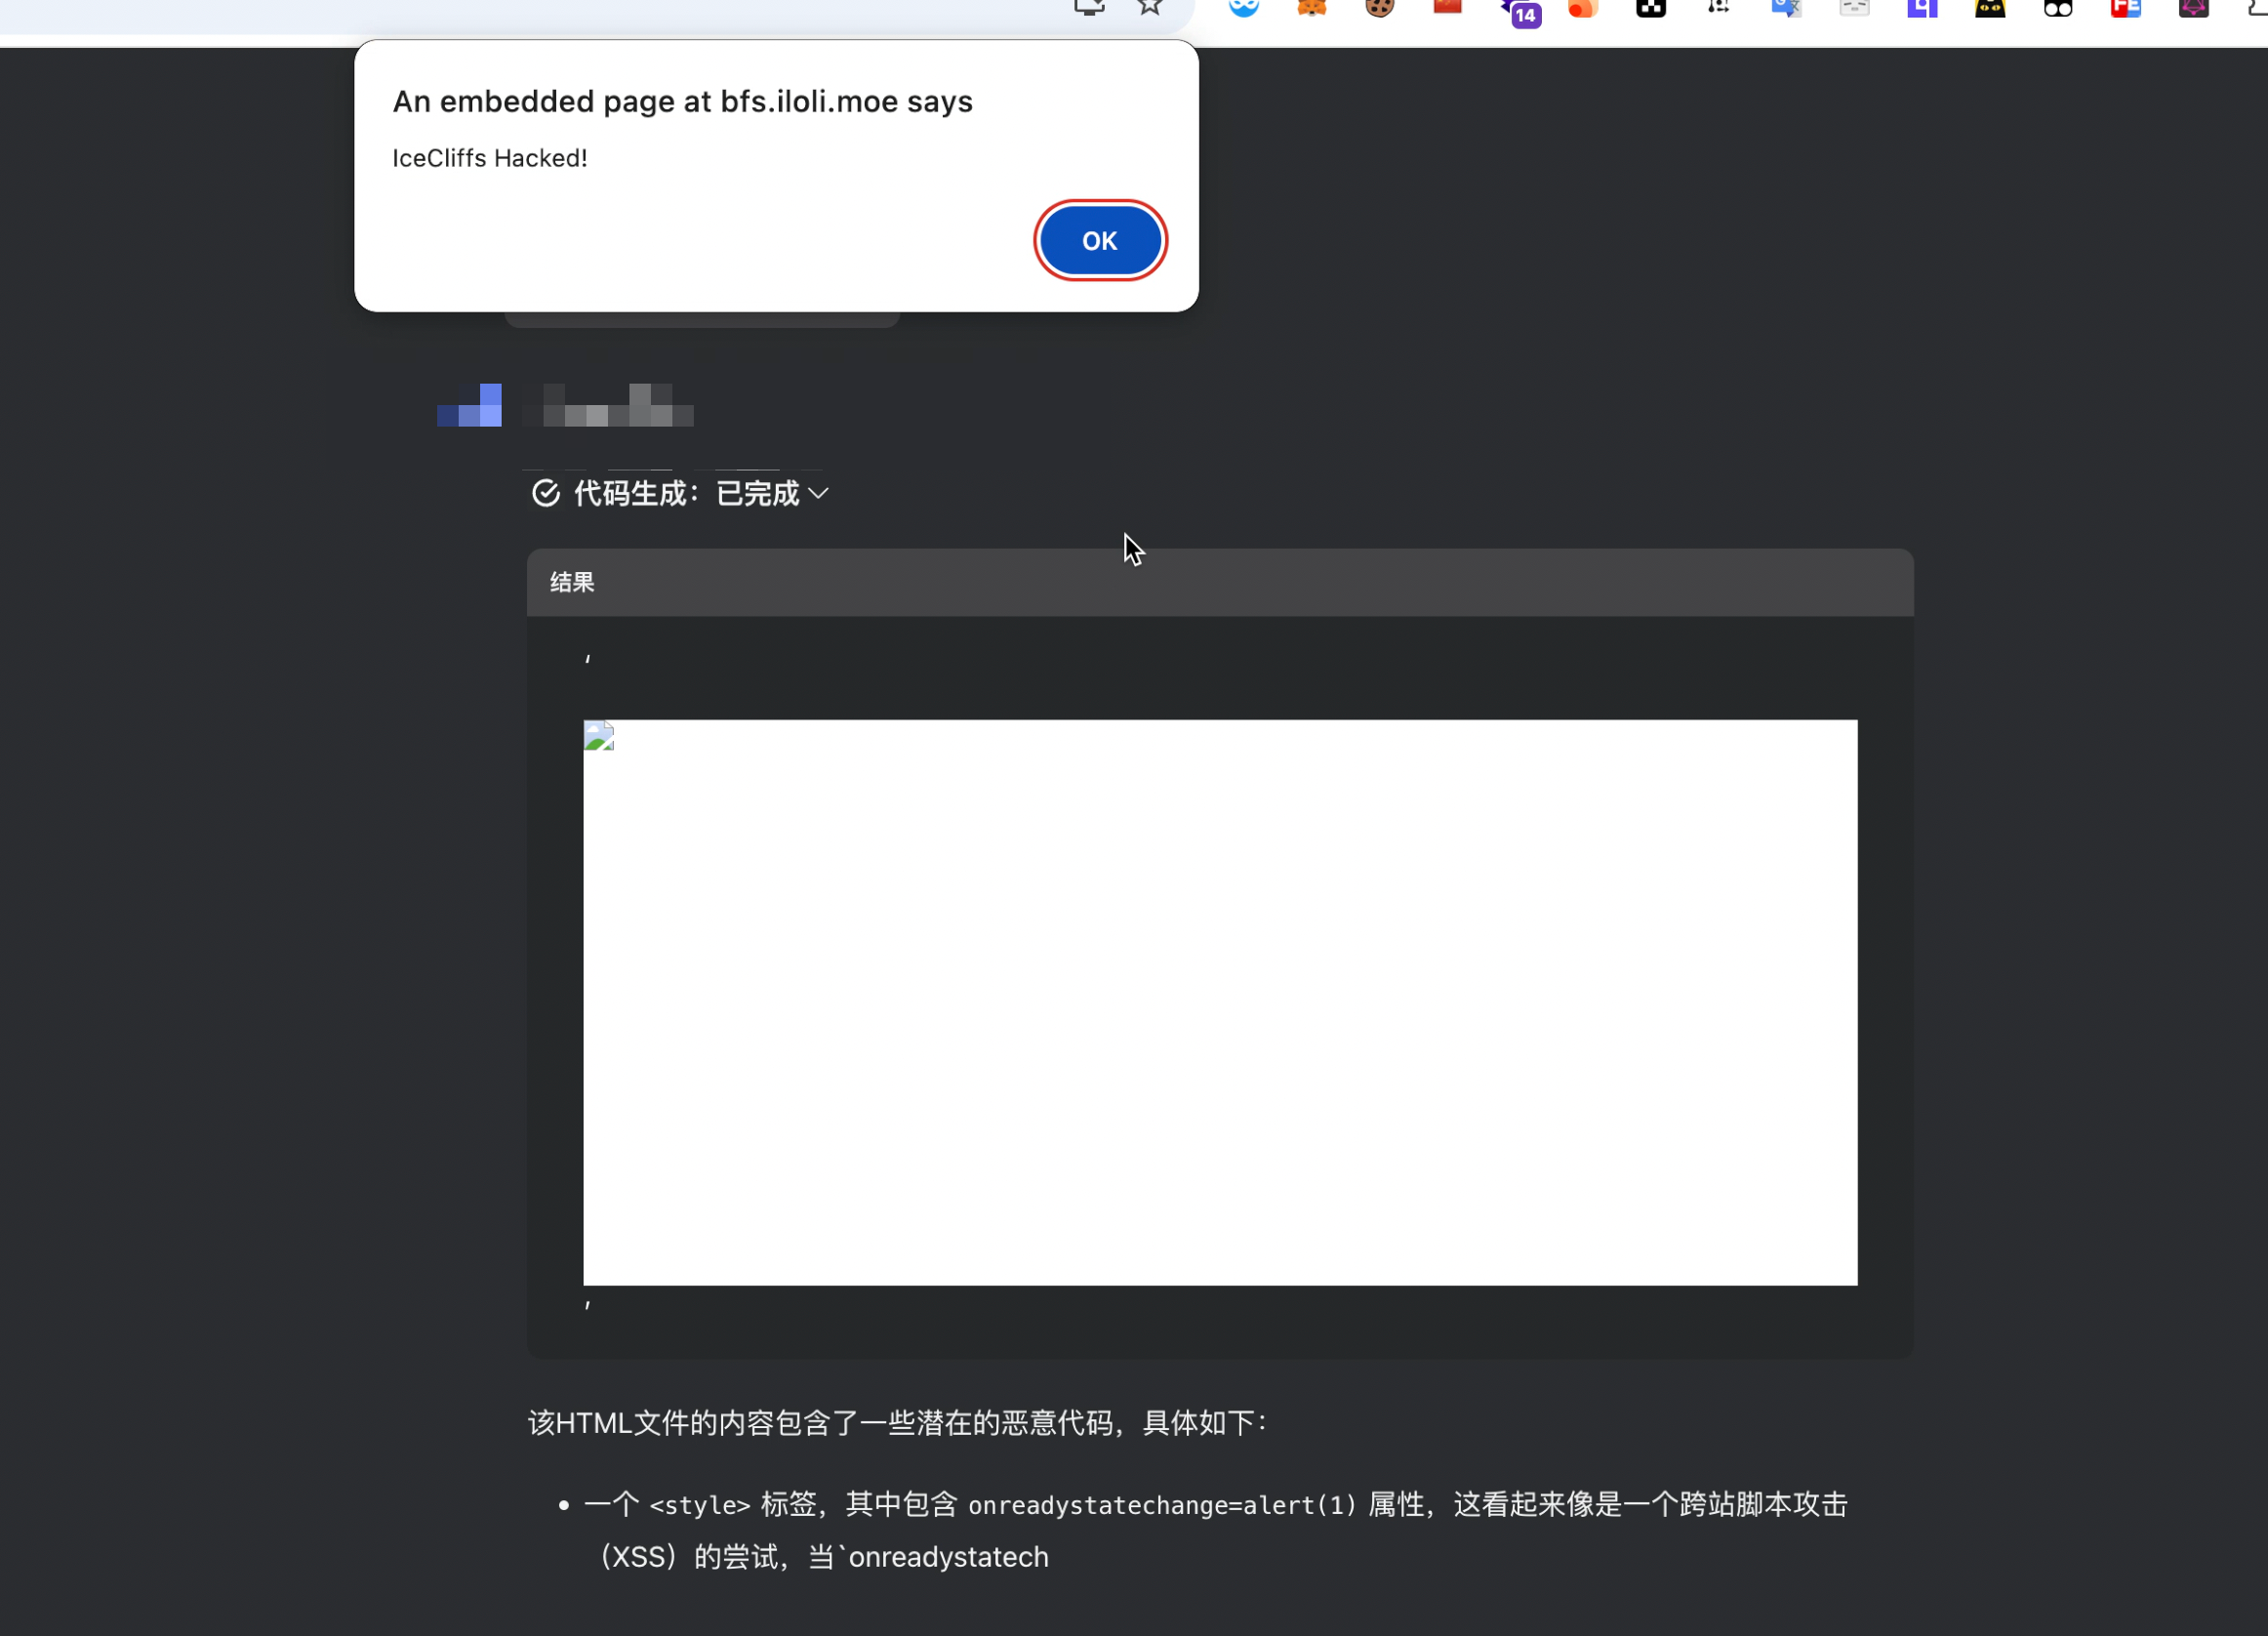
In addition, the same front end supported sharing chat conversations, so a transcript containing such markup became a stored payload that executed in the browser of any user who opened the shared record. This is the part worth emphasising from a defensive standpoint: model output is stored, re-rendered and redistributed, so it deserves the same distrust as any other user-supplied content entering a web application.
Defending against LLM attacks
Treat any API exposed to an LLM as publicly accessible.
As users can effectively call APIs through the LLM, any API that the LLM can access should be treated as publicly accessible. In practice, this means enforcing basic API access controls, such as always requiring authentication for a call.
Mitigations
- Render model output as text. Where rich formatting is genuinely required, pass it through an allow-list based sanitizer instead of trusting the model to emit safe markup.
- Treat every input channel as untrusted. Chat history, uploaded files, retrieved documents and tool output must be validated on the prompt path and again on the rendering path; the second check is the one that prevents stored payloads from reaching other users.
- Constrain what the model can reach. Give the integration a dedicated credential with least privilege, require authentication on every API call the model may make, and restrict outbound traffic from the model service to an allow-list so that prompt-driven SSRF and callback attempts fail at the network layer rather than at the model’s discretion.
- Apply a Content-Security-Policy that forbids inline script, so a missed sanitization step does not immediately become script execution.
- Log and review model interaction. Markup fragments, URL literals and outbound connection attempts in model output are useful detection signals; unexpected callbacks originating from the model host are a strong indication that prompt injection is being used to reach the network.
Case: unauthenticated access to a self-hosted model runtime
By default, some Ollama deployments are affected by unauthorized access vulnerabilities, and the trigger conditions are trivial. Most of them correspond to CNVD-2025-04094, and the vulnerability is very easy to trigger.
The exposure is structural rather than exotic: the runtime listens on all interfaces, its model listing endpoint answers without credentials, and the chat endpoint accepts requests from any client that can reach the port. The model listing response alone is already informative.
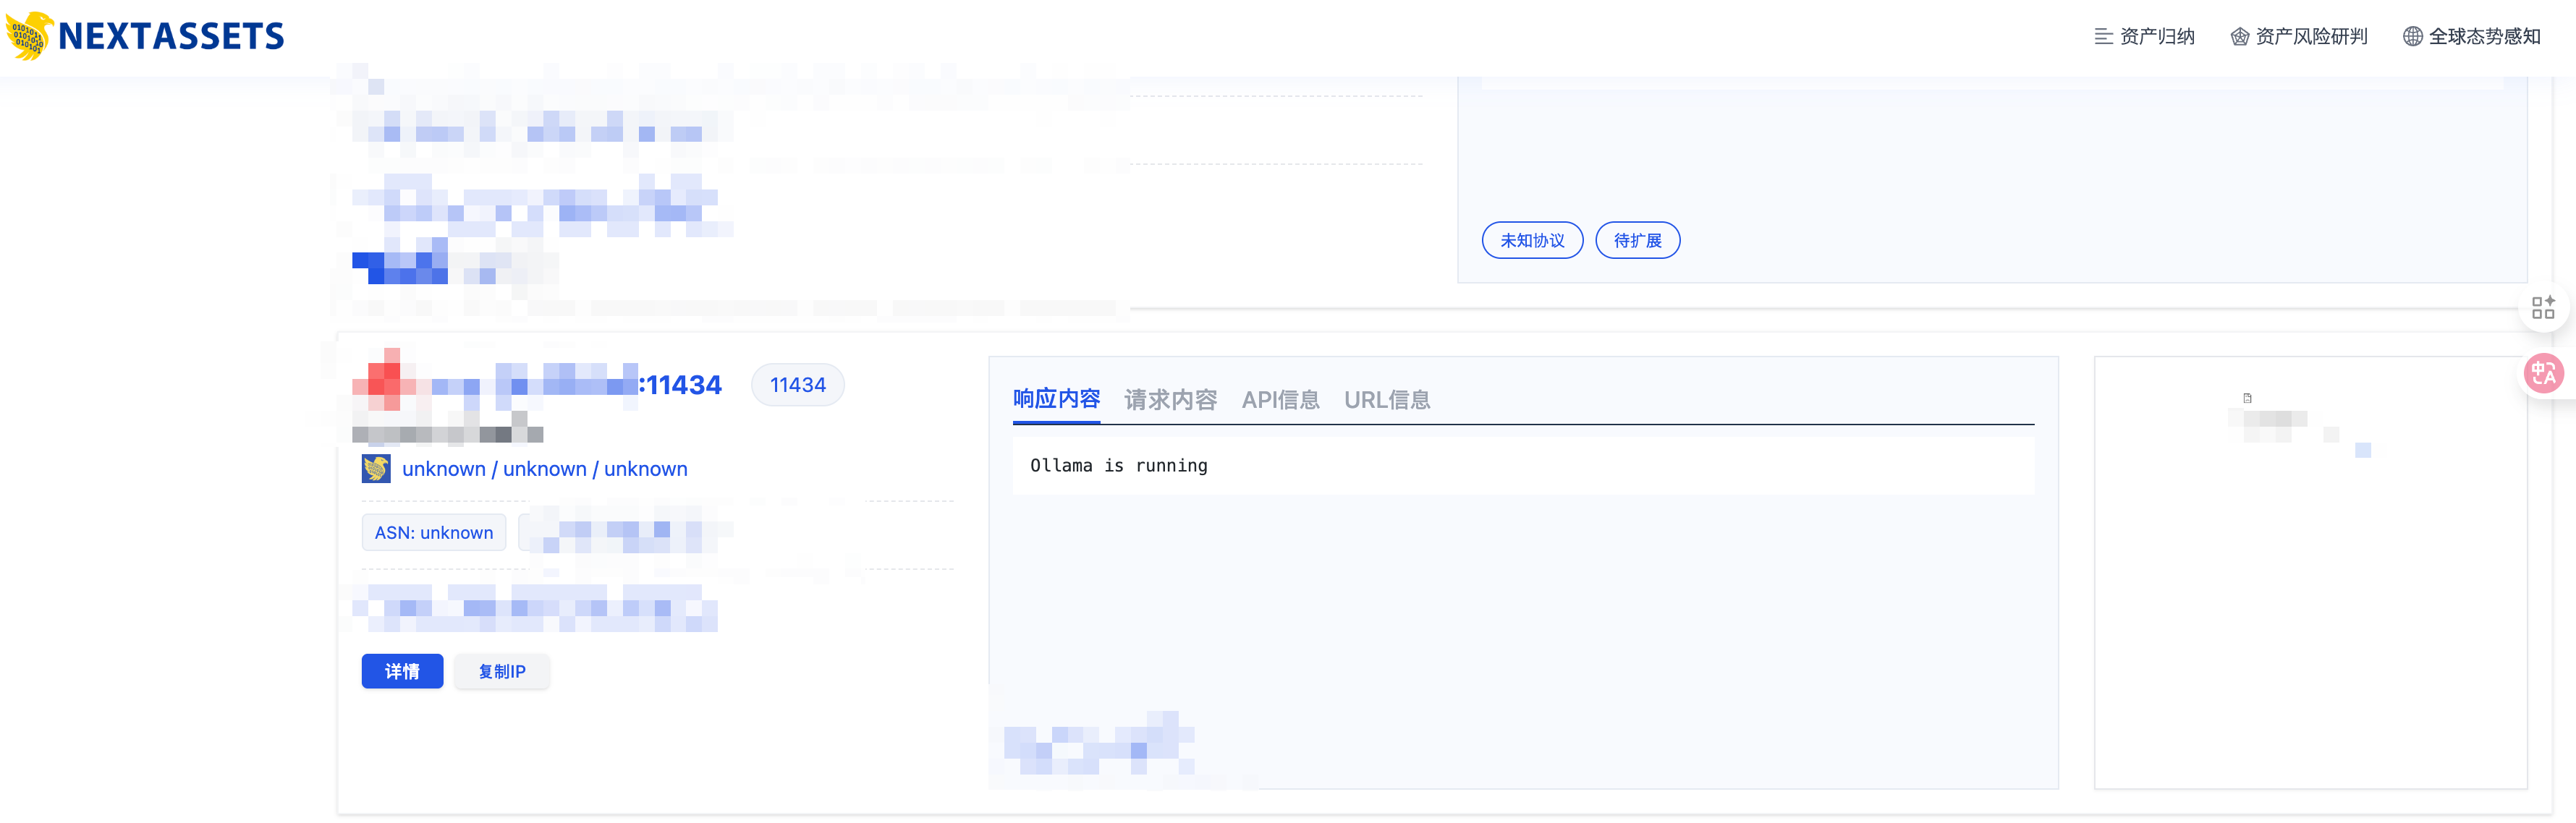
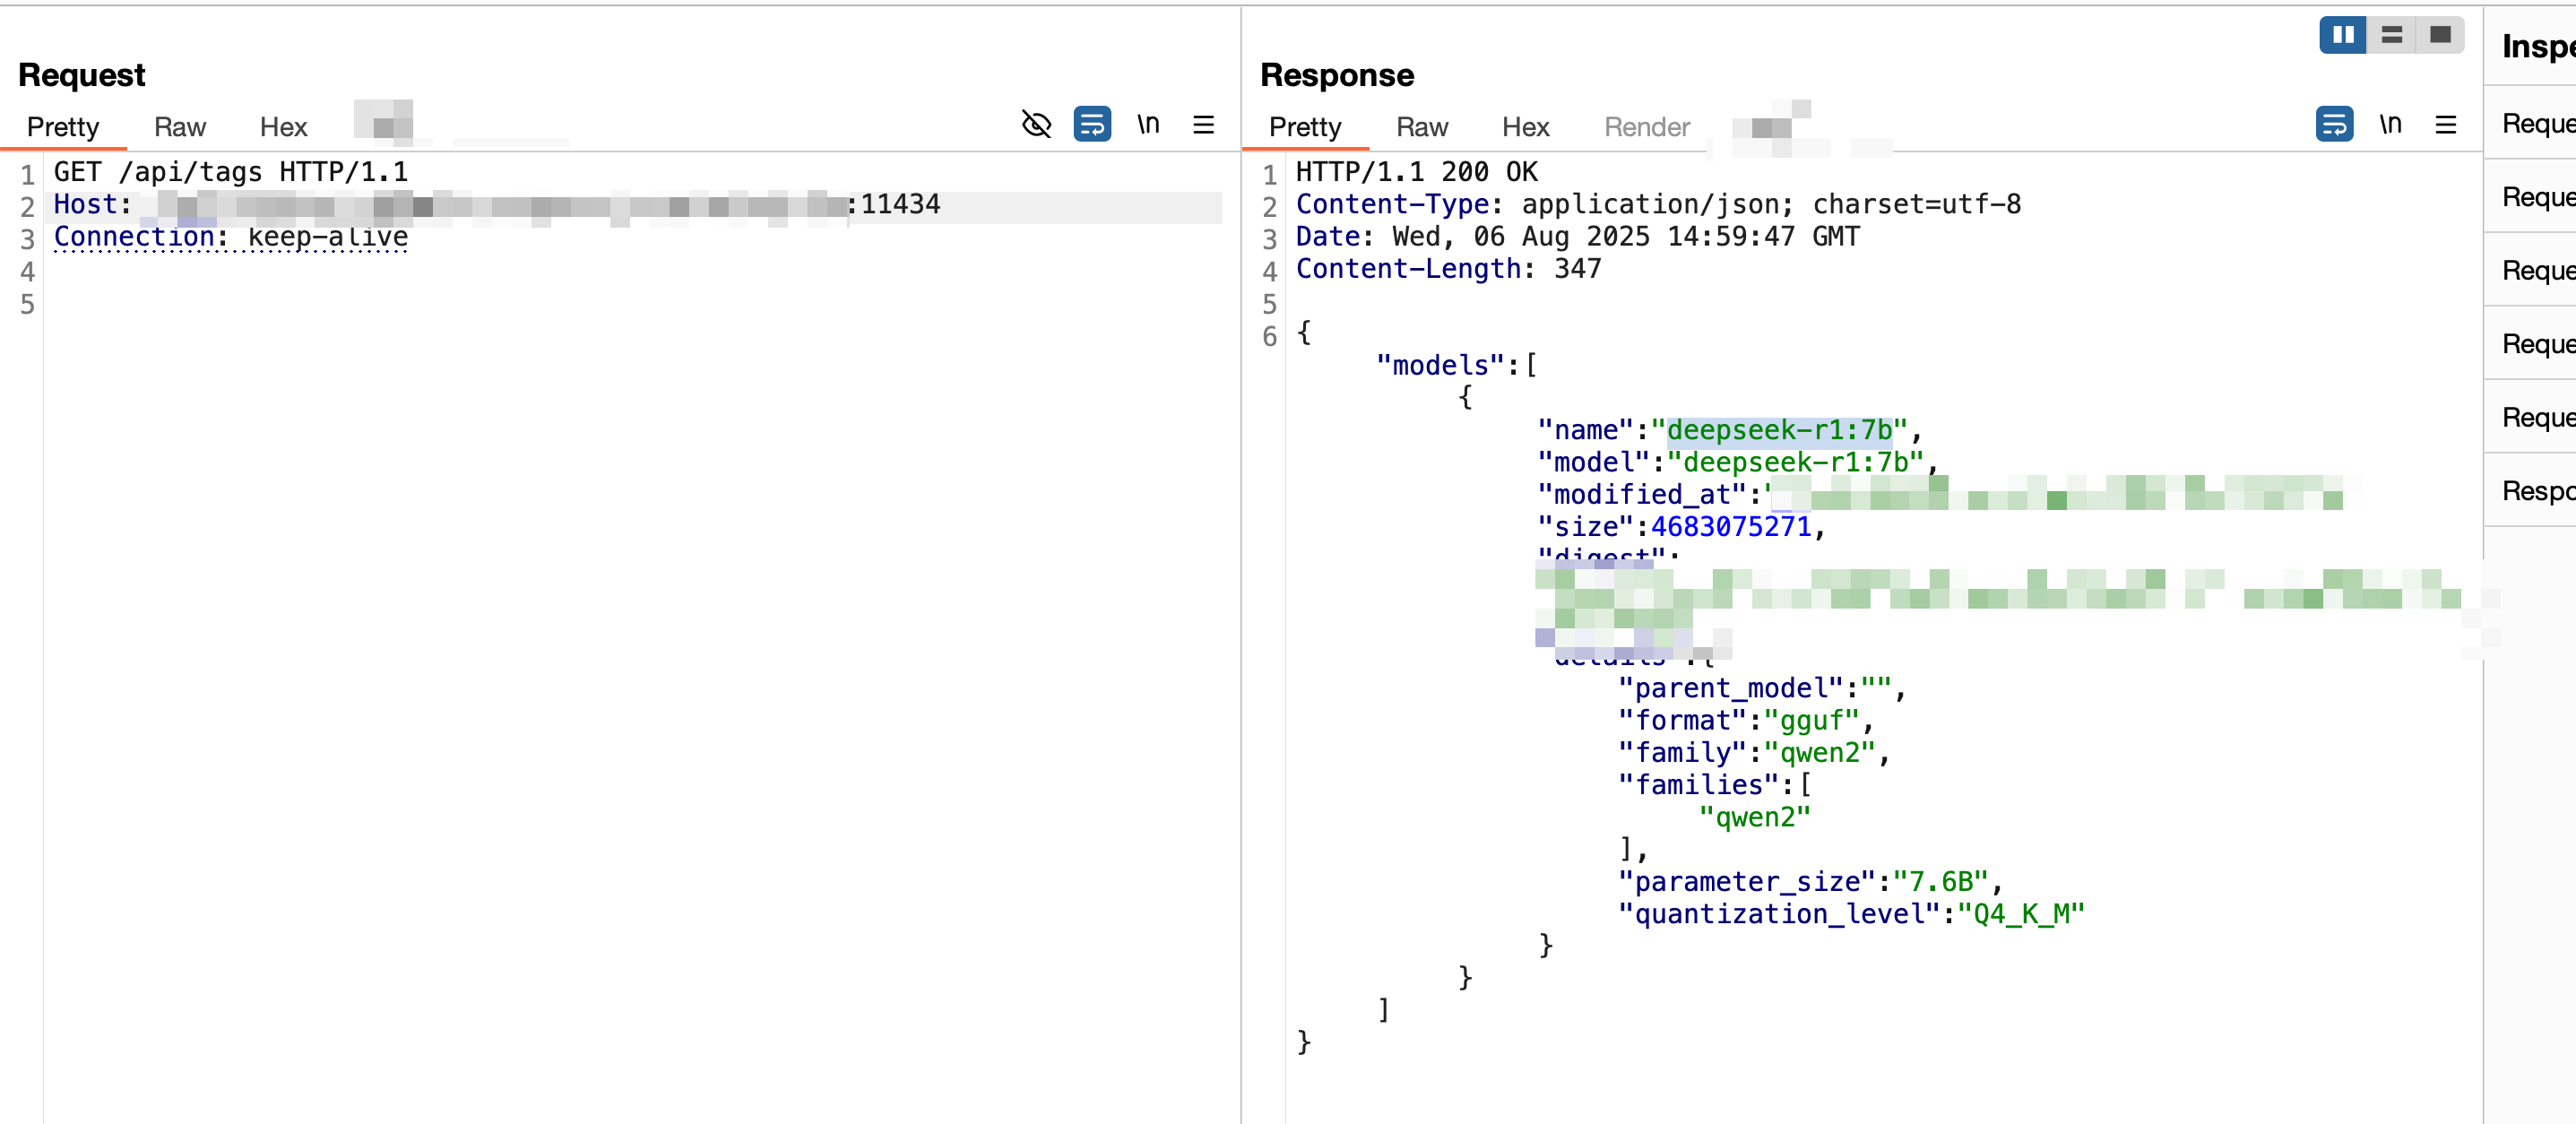
Beyond information disclosure, an exposed instance can be driven as a free inference service: any client that can reach the port can invoke the loaded model and consume its compute resources.
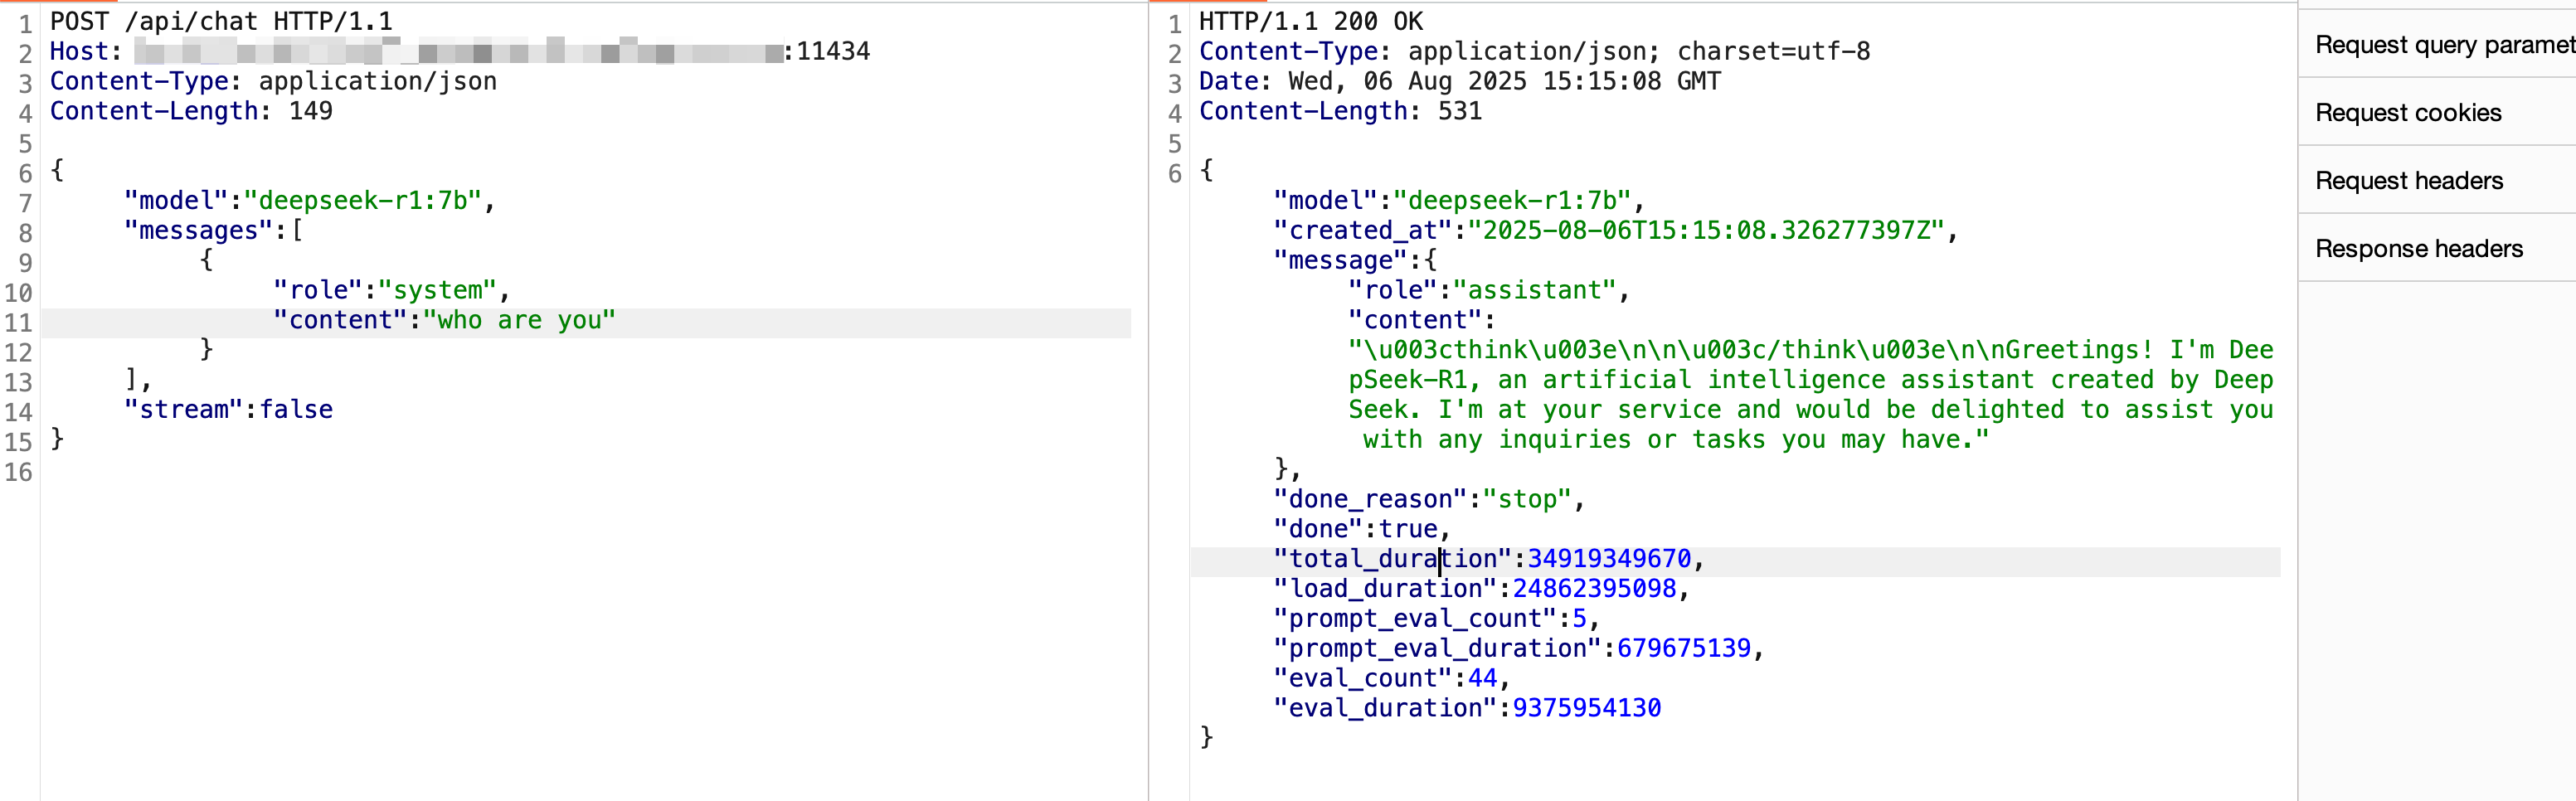
From a defensive perspective, the useful question is not how such an endpoint is called but how to tell whether an instance is exposed: check the listening address and the firewall rules covering the runtime port, confirm that authentication is enforced in front of the API rather than by the client, and review access logs for model enumeration and chat requests originating outside the expected client set. Where the runtime is only needed locally, binding it to the loopback interface and keeping the port closed at the perimeter removes the exposure entirely.
Supplementary observation